Case study Nº 04
Web app
Ops Automation Hub
Lead scoring and document extraction, with a person checking anything the model is unsure of.
- Type
- Web app
- Stack
- Next.js · TypeScript · Prisma · Trigger.dev · FastAPI · OpenAI
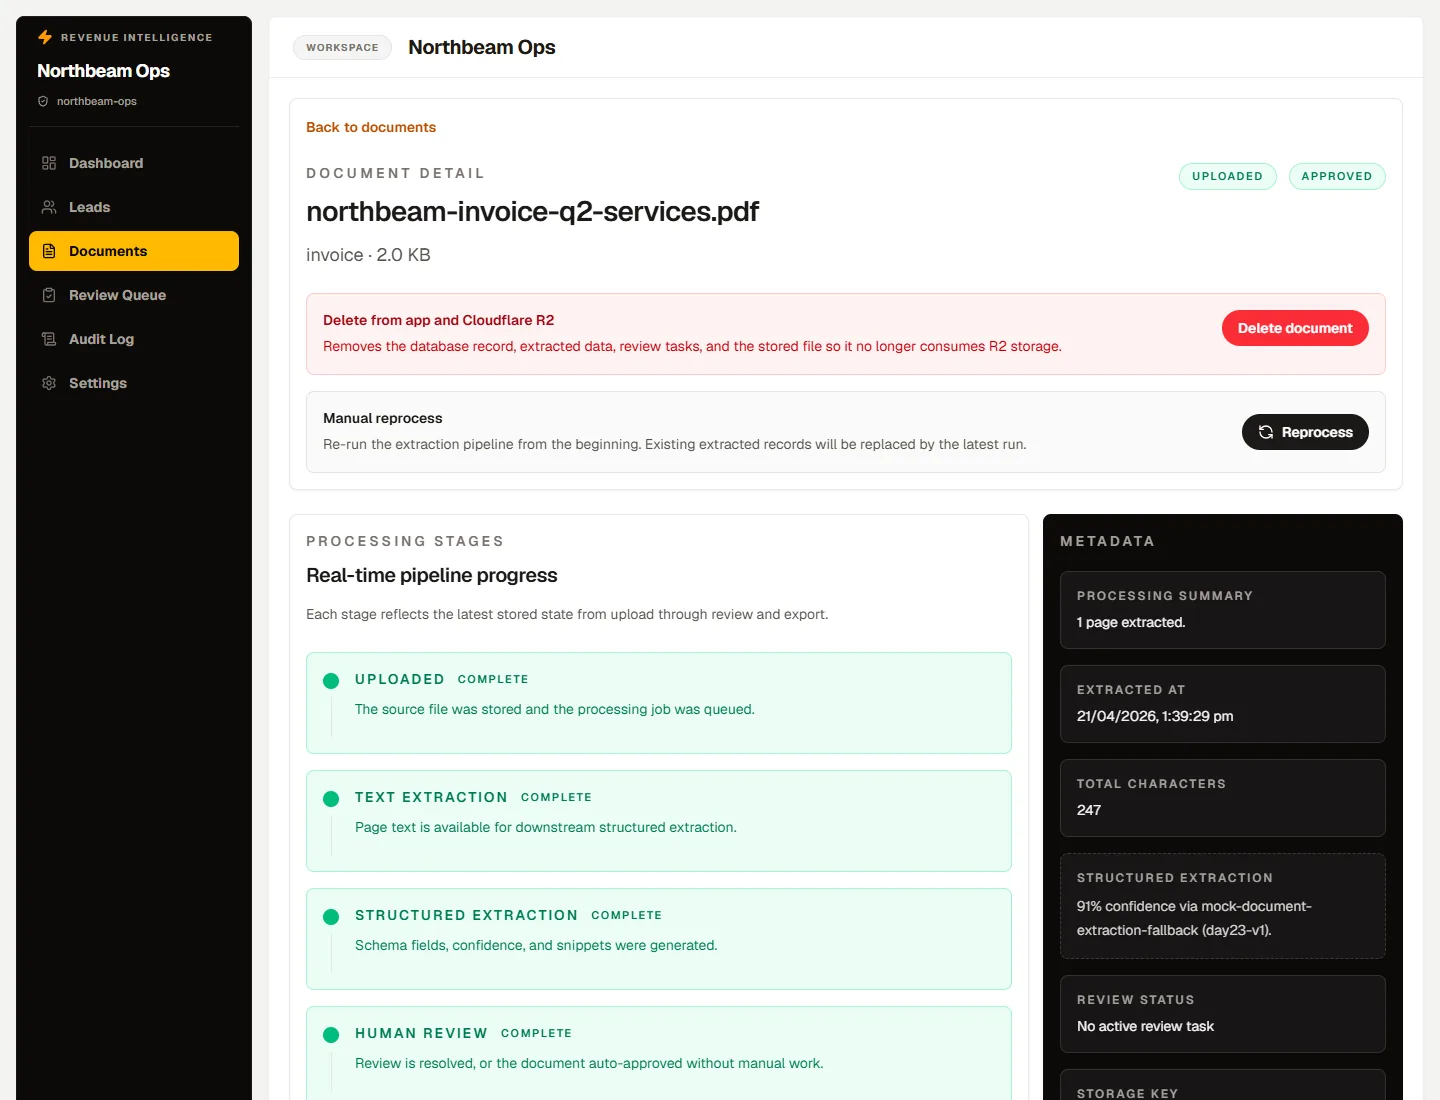
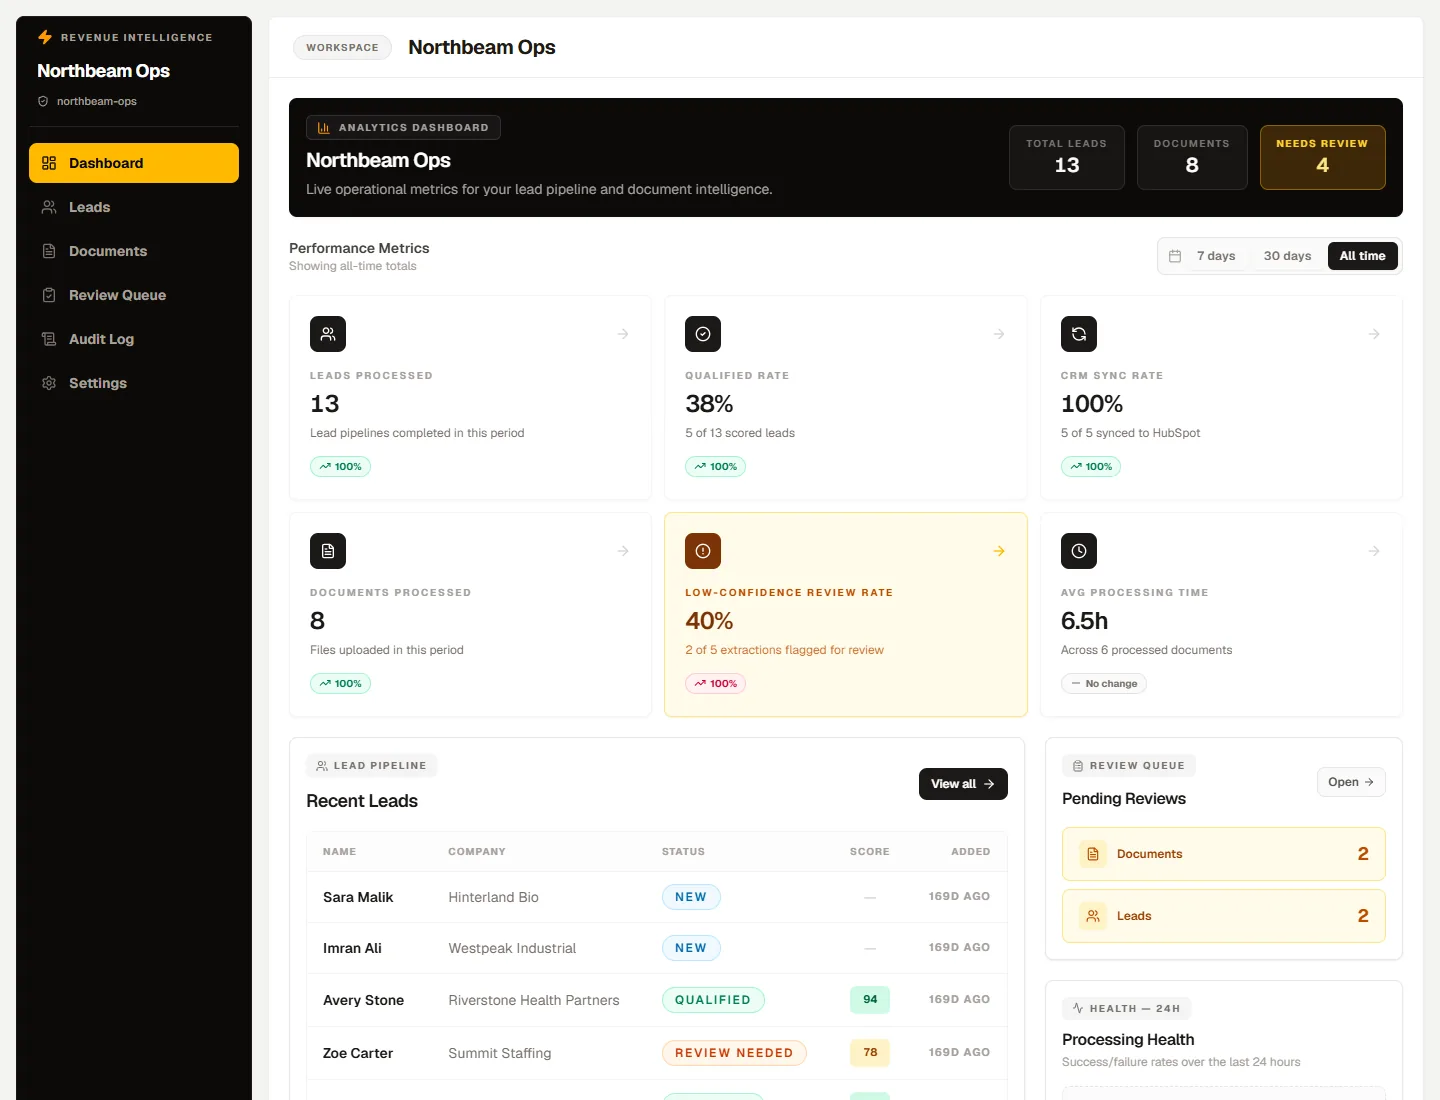
Two back-office pipelines in one app. New leads are enriched, scored and synced to HubSpot. Uploaded invoices, onboarding forms and agreements go through OCR and structured extraction, then wait for review before anything is exported.
The lead pipeline
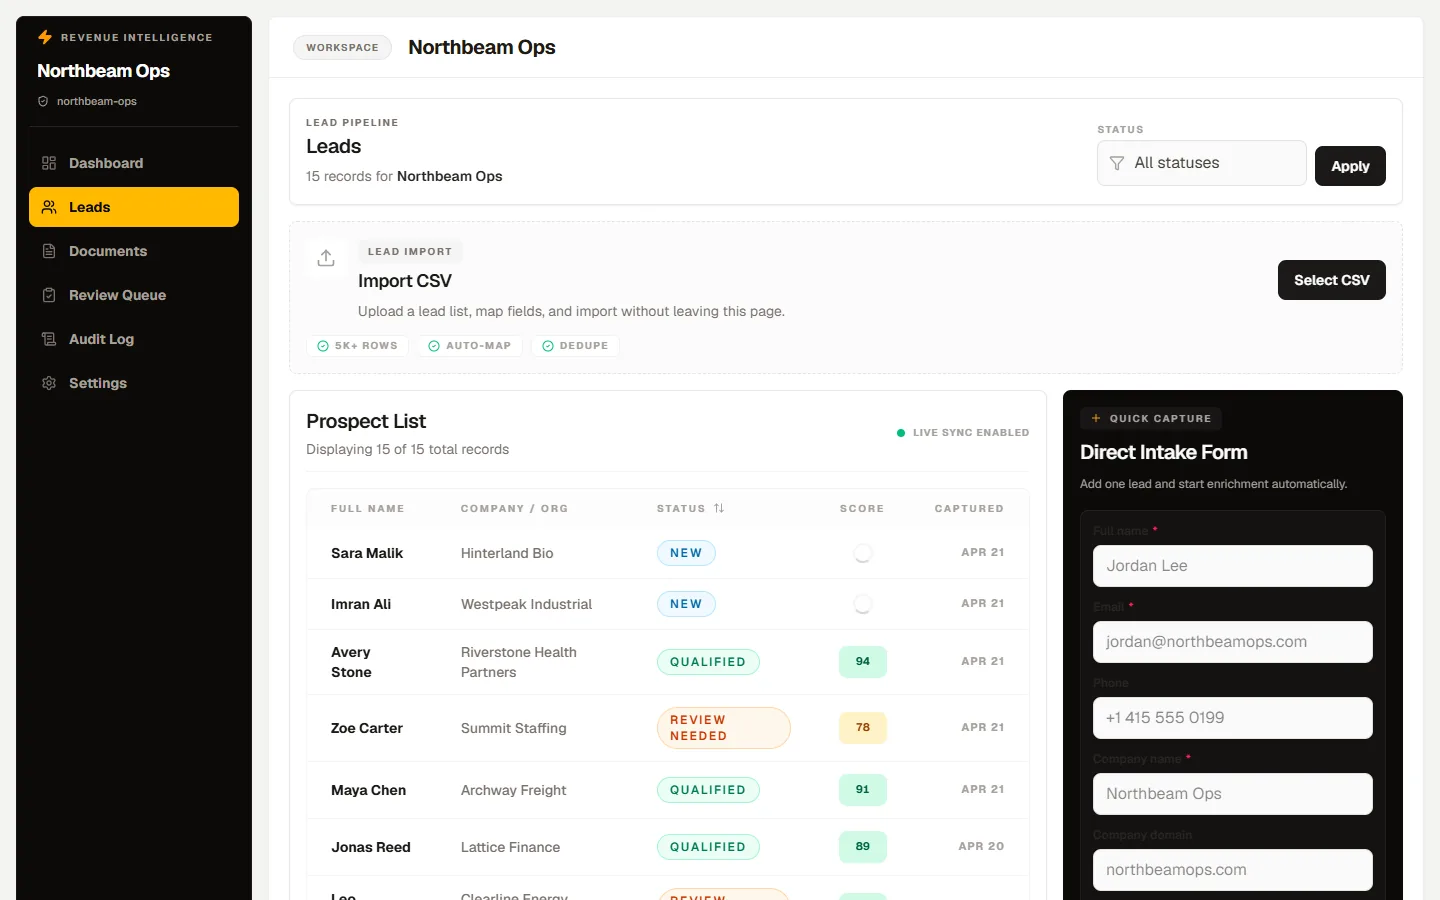
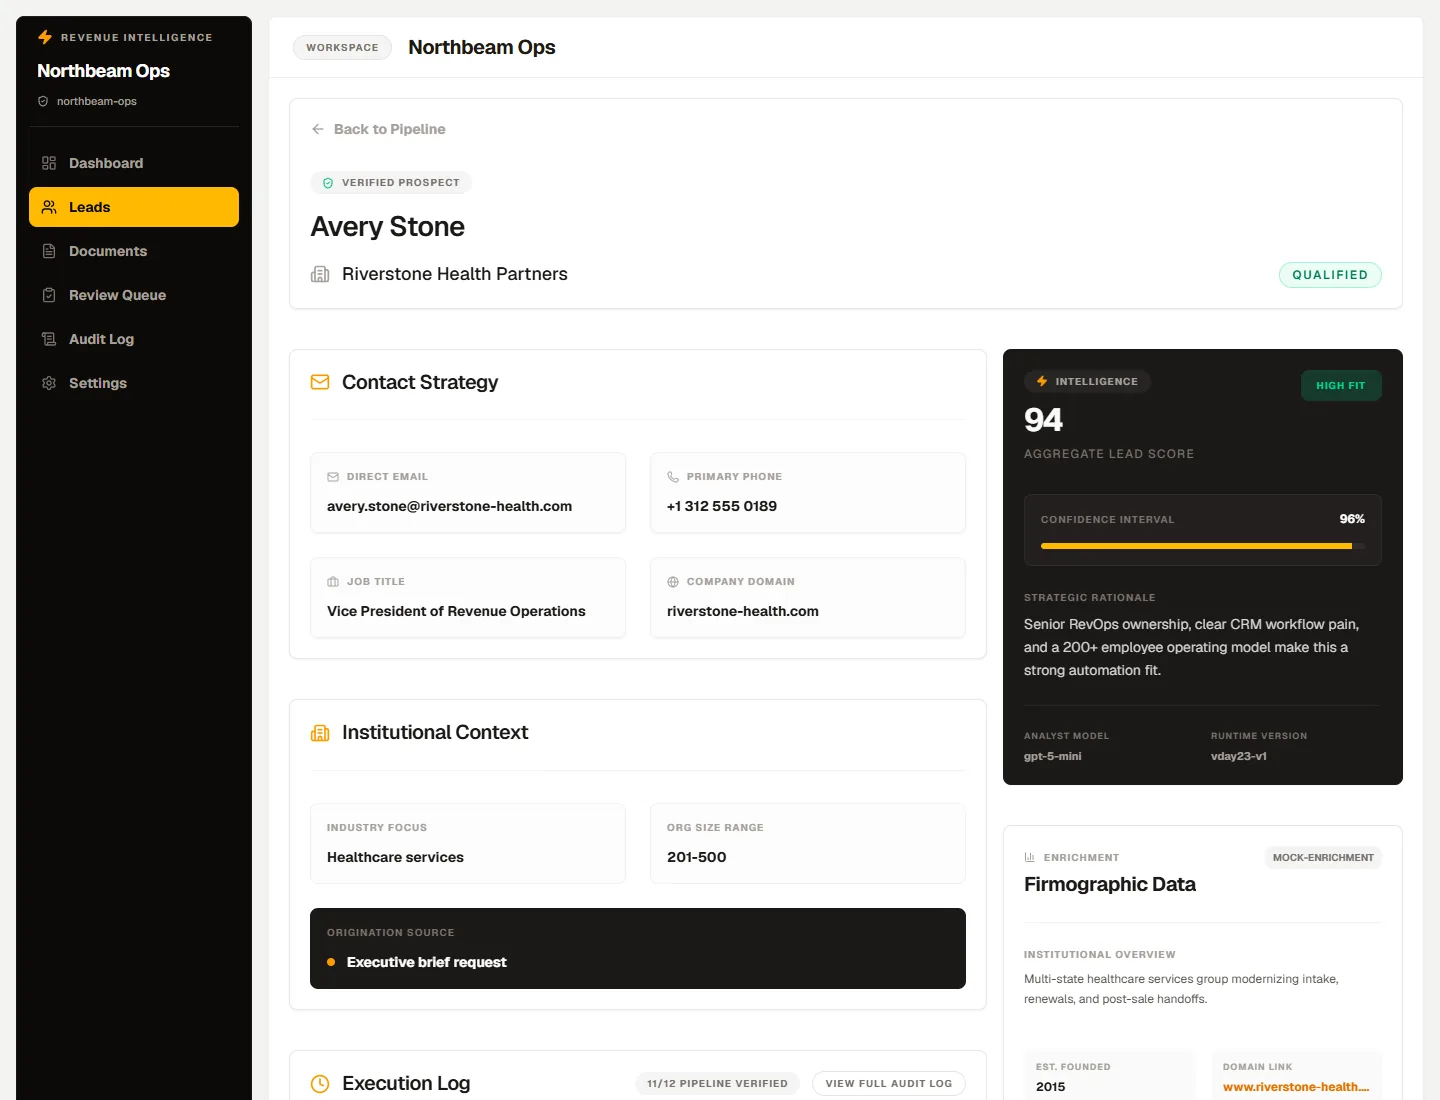
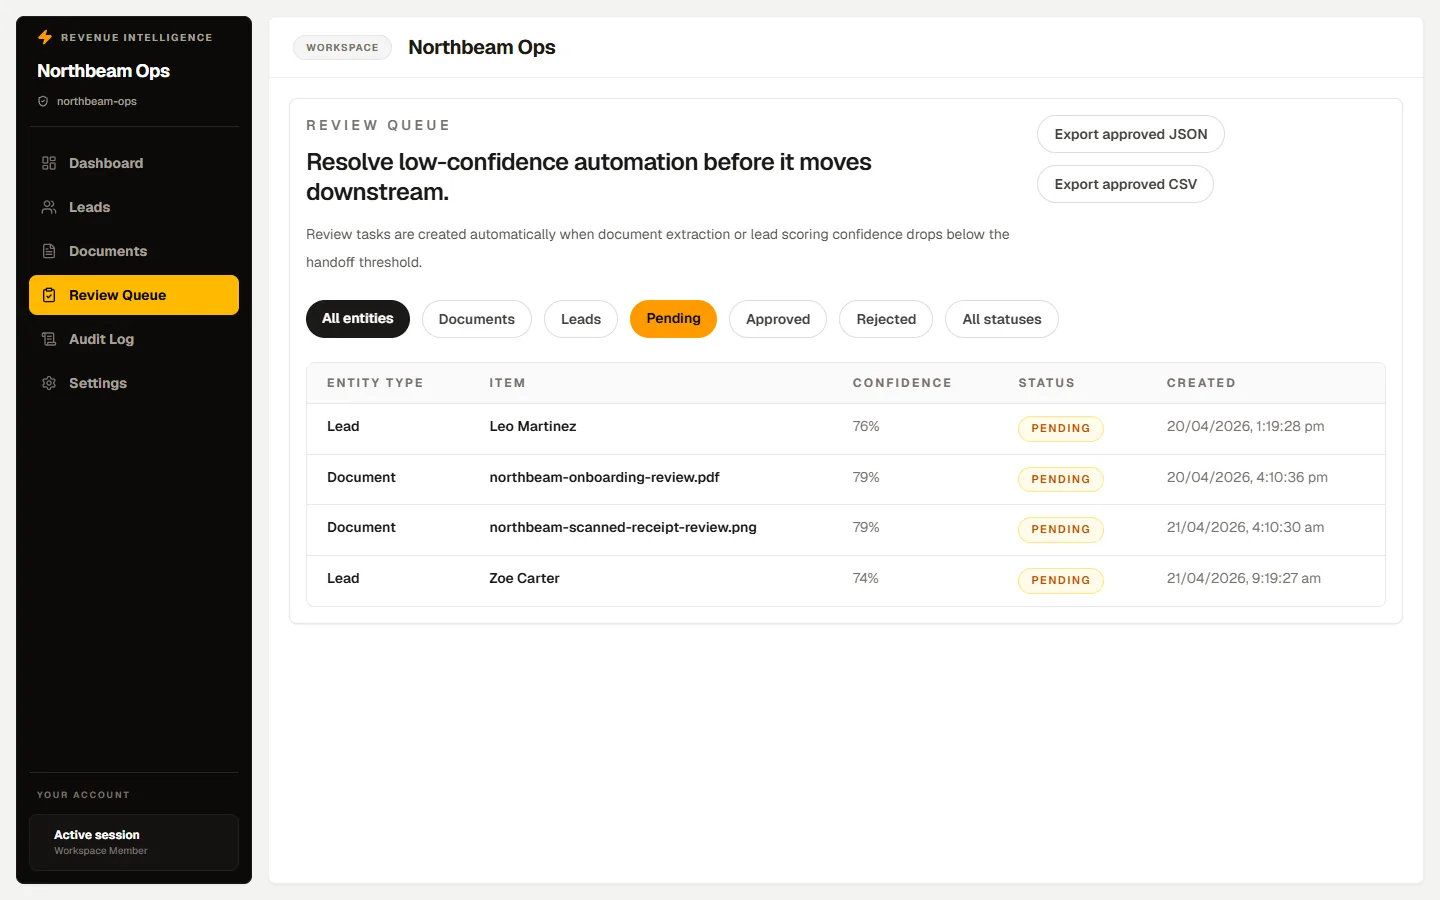
Leads come in from a hosted form or a CSV import with column mapping. A background job enriches each lead, scores it with OpenAI and routes it. Qualified leads are created or updated in HubSpot and announced in Slack, and leads the model cannot score confidently go to a review queue.
For sales, the app drafts a lead summary, a follow-up email and a meeting brief.
The document pipeline
Files are uploaded to Cloudflare R2 and sent to a separate Python service built with FastAPI, which pulls out text and tables with PyMuPDF and pdfplumber and falls back to Tesseract OCR for scans. The app then extracts structured fields, each with its own confidence, and shows them in a review form before export.
Decisions worth mentioning
Anything slow or likely to fail runs as a Trigger.dev task with retries, so the web app never waits on OCR or the OpenAI API.
Every lead and document has an activity timeline and an audit log, and the prompt templates are versioned in code, so a change in AI output can be traced to a change in the prompt. Workspaces are scoped by Clerk organizations.
Plates